Jira local LLM integration: pin one HR project to LM Studio with CogniRunner
Mihai Perdum
Author
15 min readOctober 14, 2026
Key takeaways
END STATE: one Jira Cloud project whose AI checks are answered by qwen/qwen3.6-35b-a3b in LM Studio on your own Mac, while the other projects on the site keep using the site's cloud provider.
On 14 October 2026 I sent the same HR request 8 times with a sentence about back surgery in it and 8 times without. Jira refused it 8 of 8 and passed it 8 of 8, and LM Studio's log held all 16 requests.
The model answered in 0.6 to 0.8 seconds. The person clicking waits about 3 seconds, and my first transition took 6.4.
With a wrong token on the project, Jira answered HTTP 204 and the request moved to In review with the health sentence still in it. The site's provider got nothing, and no model read the text.
An unpinned project with the same check and the same text was answered by openai/gpt-6-luna, with 0 requests in LM Studio's log.
The text does leave Atlassian. It crosses the public internet through a Tailscale Funnel, LM Studio's log file on the Mac keeps the model's answers, and CogniRunner stores the first 300 characters of the field with each log row for up to 30 days.
This is a Jira LLM integration where the LLM is local. One Jira Cloud project sends its AI checks to qwen/qwen3.6-35b-a3b in LM Studio on our Mac Studio, and the other projects on the site stay on the cloud provider the site already uses.
I ran it on 14 October 2026 with an HR request that mentions a colleague's sick leave after back surgery. A check on the Send for Review step is meant to stop that. I sent the request 8 times with the sentence and 8 times without it, with a different salary figure each time. Jira refused it 8 of 8 and passed it 8 of 8. LM Studio's log held all 16 requests, and the person clicking waited about three seconds.
Then I saved a wrong token on the project to see what happens. I expected a refusal. I got HTTP 204: the request moved to In review with the surgery sentence still in it. So the cloud provider got nothing, and the sentence went to the approvers with no check at all. Step 8 has you do the same on your own site, so you know what it looks like before HR depends on it.
Illustration, generated locally with FLUX. One project's requests go to the computer on the desk while the other projects on the site keep going to the cloud. The mug is optional.
The routing is done by CogniRunner, the Jira app we build. We recorded a two-and-a-half-minute video of this on our demo site. It shows CogniRunner 1.33.5, and I ran a development build of 1.34.0 on our test site. The screens in steps 4 to 7 are the same in both.
Note
Prerequisites
A Jira Cloud site with CogniRunner installed, and a CogniRunner admin. I'd use 1.34.0 or later (the Marketplace calls that build 7.16.0, released 12 October 2026).
An AI provider already saved in CogniRunner's Settings for the site. Mine was OpenRouter with openai/gpt-6-luna. The provider tutorial covers that part.
A Mac that stays awake, with LM Studio 0.4.0 or later (API tokens need it). Mine was 0.4.23 on a Mac Studio, Apple M3 Ultra, 96 GB.
Memory for the model. LM Studio's catalogue page says "Minimum system memory 20 GB" for qwen/qwen3.6-35b-a3b, and the 4-bit build I loaded is 20.43 GB by itself. I haven't tried a smaller Mac.
A Tailscale account with Funnel allowed for the Mac. Tailscale's Funnel page lists what that needs: v1.38.3 or later, MagicDNS, HTTPS certificates and the funnel node attribute. I had 1.98.5.
A company-managed Jira project whose workflow you can edit.
Four words I use all the way down. A validator is a check Jira runs when somebody moves a request from one status to the next, and it can stop the move. Forge is Atlassian's platform that CogniRunner runs on, in Atlassian's cloud. A pin is CogniRunner's setting that sends the AI calls for runs on one project's issues to a provider you choose for that project. And fail open means that when the check can't run, the move is allowed.
1
Load the model and start the server
qwen/qwen3.6-35b-a3b in LM Studio, with an API token required.
2
Expose LM Studio over a Tailscale Funnel
an https address Atlassian's cloud can reach.
3
Save the address and the model in Settings
without making LM Studio the site's provider.
4
Pin one project
Agents, Setup, Project configuration, then the project's own token.
5
Add the validator
one prompt on Send for Review, reading the Description.
6
Send the request twice
once with the health sentence and once without.
7
Read LM Studio's log
both requests should be there, and an unpinned project's should not.
8
Save a wrong token once
and find the FAIL-OPEN row it leaves.
Where the text goes, and what happens when the Mac can't answer
Somebody clicks Send for Review. Jira calls CogniRunner's validator, which runs on Forge. CogniRunner reads one field of the request, here the Description, and looks up the project. If the project is pinned, the call goes to the address saved for that provider. Otherwise it goes to the site's provider.
For my pinned project that address is a Tailscale Funnel. Tailscale's docs say the Funnel relay "creates a TCP proxy to your device over Tailscale", and that the Tailscale server on the device "terminates the TLS connection and passes the decrypted request to the local service". So the Description leaves Atlassian, crosses the public internet encrypted, and is decrypted on the Mac. It doesn't stay in the office. For this one project it also isn't sent to OpenAI, Anthropic or any other model vendor. I can't promise more than that.
Some of it stays behind in two logs. LM Studio keeps a server log file on the Mac. On mine (0.4.23, with the settings I had) this morning's file holds each of the model's answers in full, and 8 of those lines name the sick leave. The request itself is in there as a cut-down stub. CogniRunner stores the first 300 characters of the field with each log row for up to 30 days, and a busy site drops old rows sooner. Its Execution Logs tab shows the model's reason, and I read the stored text back over the app's REST API. So think about who can open those two places.
And when the Mac can't answer, by default the request goes through. The validator fails open and writes a row saying why. 1.34.0 has a switch, off by default, that holds the move while a slow self-hosted model finishes (it's under If it didn't work). I didn't find one for an error such as a wrong token. If your HR lead needs a hard stop, this isn't one.
Why would you want it anyway? I think the common case is a project where now and then somebody types a thing you'd prefer no model vendor to receive, on a site where the other projects are fine on a cloud model. I didn't find that choice for Rovo on the two Atlassian pages I read, the AI trust page and the support page for Atlassian-hosted LLMs. The AI trust page says "By default, Rovo leverages dynamic routing between models", and the one option it describes is for Cloud Enterprise: "Eligible customers can elect to use only Atlassian-hosted LLMs". Two open suggestions on Atlassian's tracker ask for more. AI-973, "Allow admins to configure Atlassian Intelligence with custom LLM", had 32 votes when I read it on 14 October. AI-110, which asks to switch AI on or off for a specific space or project, had 139.
Step 1. Load qwen3.6-35b-a3b and start the LM Studio server
Download the model in LM Studio and load it. I used Qwen3.6-35B-A3B, which carries an Apache 2.0 licence tag on Hugging Face, in LM Studio's MLX 4-bit build with a 16,384-token context. If you're choosing between the MLX and GGUF builds on a Mac, I measured that in MLX vs GGUF on Apple Silicon.
Then open LM Studio's Developers page, start the server, and in Server Settings turn on Require Authentication. In the same settings, click Manage Tokens, then Create Token, and keep the token for step 4. LM Studio's authentication page is blunt about why: "By default, LM Studio does not require authentication for API requests." You're about to put this server on the internet.
My server was already set up this way from the video, so I describe those clicks from LM Studio's docs. I did run the check today. The lms command ships with LM Studio (on my Mac it lives in ~/.lmstudio/bin).
bash
1lms ps
text
1IDENTIFIER              MODEL                   STATUS    SIZE        CONTEXT    PARALLEL    DEVICE    TTL
2qwen/qwen3.6-35b-a3b    qwen/qwen3.6-35b-a3b    IDLE      20.43 GB    16384      4           Local
bash
1lms server status
text
1The server is running on port 1234.
Check:lms ps should show your model with a size and a context, and lms server status should print the port. Copy the identifier from the first column. You'll need it in step 3, character for character.
Step 2. Expose LM Studio over Tailscale Funnel with https and an API key
CogniRunner's call is made from Atlassian's network. It can't reach localhost on your Mac, and it only speaks https. A Tailscale Funnel gives the Mac a public https name with a real certificate, and you don't have to open a port on your router.
I mounted LM Studio under a path, because the same Mac serves other things on that name. This is the form tailscale funnel --help and Tailscale's command reference give for it on 1.98.5:
I don't have the exact line I typed back then in my shell history, and I didn't re-run the mount today because other things on this Mac depend on it. Today I ran the status and a request from the public side. I've masked the tailnet name, and from the status I cut everything this Mac serves besides /lmstudio (other ports and other paths).
1{
2  "error": {
3    "type": "invalid_request",
4    "code": "invalid_api_key",
5    "message": "An LM Studio API token is required to make requests to this server, but none was provided using the Authorization header using the 'Bearer' scheme (i.e., 'Authorization: Bearer $LM_API_TOKEN'). Learn more at: https://lmstudio.ai/docs/developer/core/authentication."
6  }
7}
8HTTP 401
Check: the curl should return HTTP 401 with invalid_api_key. That tells you the Funnel reaches LM Studio and that LM Studio turns away a caller with no token. If you get a model list back, go to step 1 and turn on Require Authentication, because right now anyone with the address can use your Mac. With the token in an Authorization: Bearer header, the same address listed my model as mlx, 4bit, loaded.
Step 3. Save the LM Studio address and model in Settings, without switching the site
A pin has no address field. It uses the LM Studio address saved in CogniRunner's Settings. So that comes first.
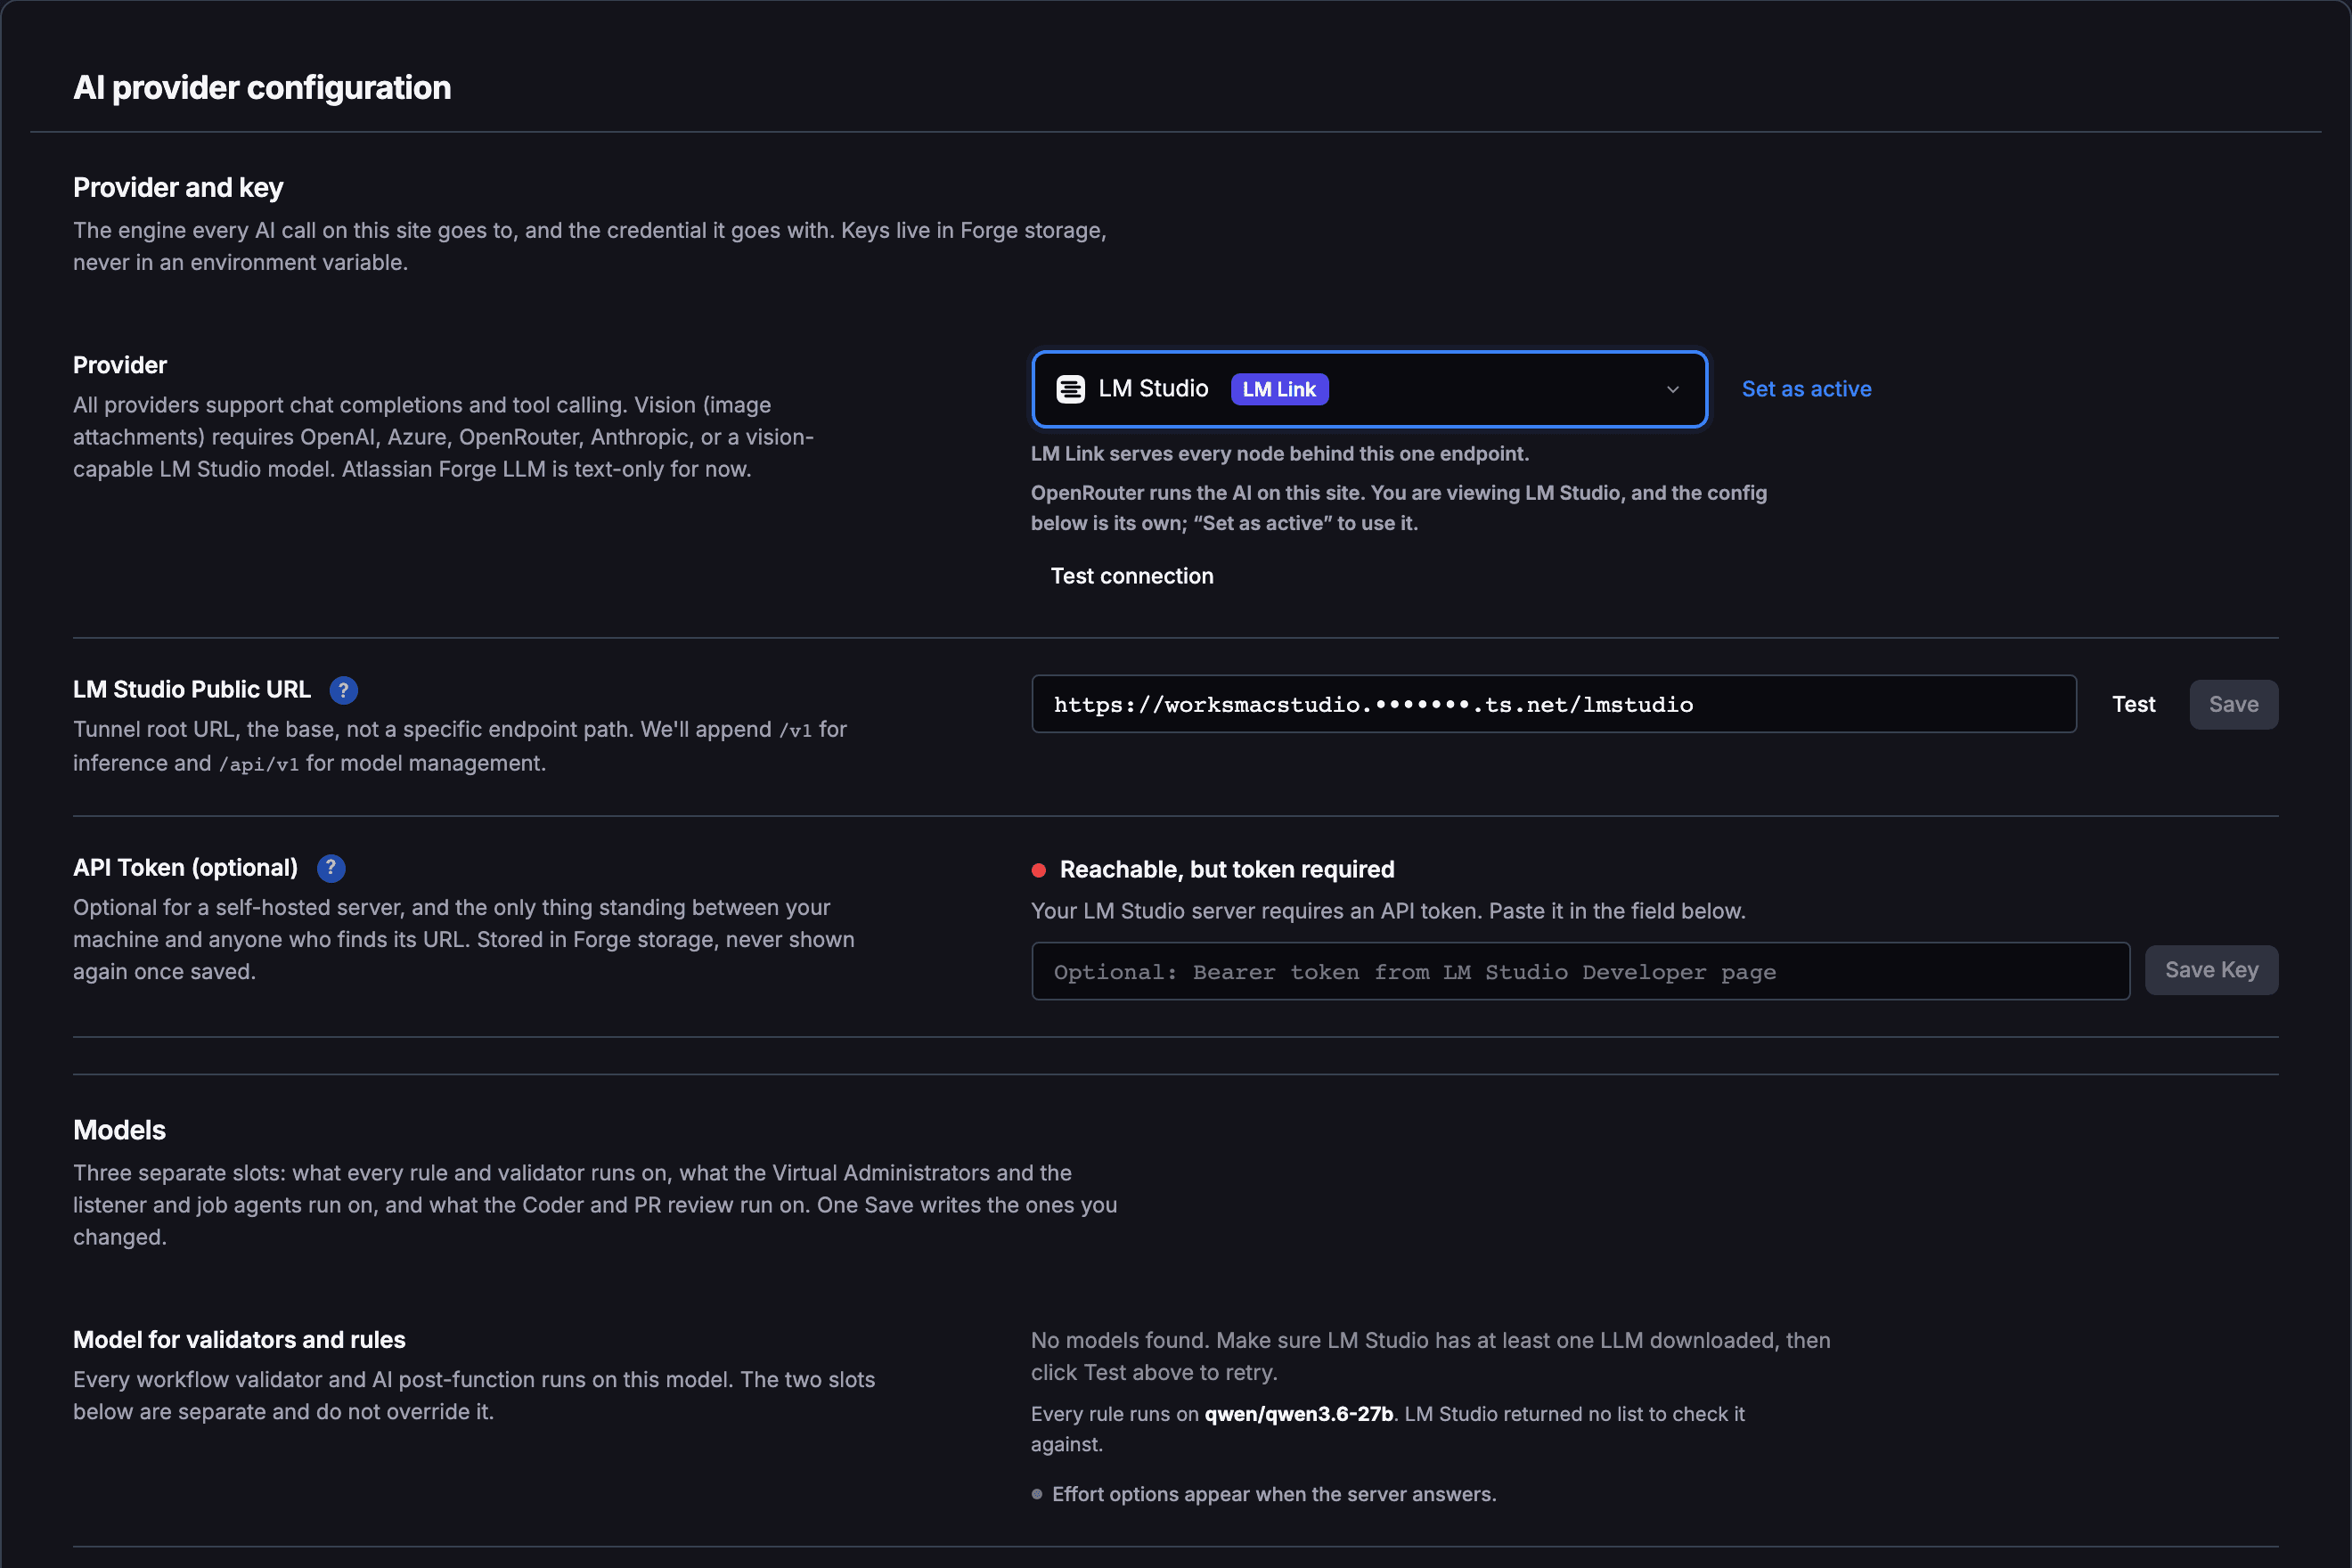
Open CogniRunner's admin page and the Settings tab. In the card called AI provider configuration, open the Provider list and pick LM Studio. Picking it only shows you LM Studio's settings. The site keeps running on the provider it had, and the card says so under the list:
text
1OpenRouter runs the AI on this site. You are viewing LM Studio, and the config below is its own; “Set as active” to use it.
Leave Set as active alone. Put your Funnel address in LM Studio Public URL, as https://<your-mac>.<tailnet>.ts.net/lmstudio with no endpoint path after it, and click Save.
Settings on a development build of 1.34.0, on our test site, with LM Studio picked for viewing. The line under the list says OpenRouter still runs the AI on this site. No token is saved in Settings on this site, so the status reads Reachable, but token required and the model row has no list.
I looked at this screen today and clicked nothing on it but the list, because the address on our test site was already saved from earlier work. So the labels are from the page, and what the Save click does (it saves the address and leaves the active provider alone) is from our code.
The model is where I'd have lost time. A pinned project asks for whatever model the LM Studio row called Model for validators and rules names. A project has no model field of its own. On my site that row still said qwen/qwen3.6-27b from an earlier experiment, while LM Studio had qwen/qwen3.6-35b-a3b loaded.
There's a catch in how you change it. As the screenshot shows, with no LM Studio token saved in Settings the row has nothing to pick from: "No models found." I didn't want a site-level token on the test site, so I set the model through our development test hook, which you won't have. I expect that pasting the token into API Token (optional) and clicking Save Key gives you a model list and a Save models button that works. I haven't watched that happen on 1.34.0. So read the audit log afterwards. Mine recorded the change with this sentence:
text
1Set the LM Studio model to qwen/qwen3.6-35b-a3b (was qwen/qwen3.6-27b).
Check: the Provider list should still show your cloud provider as Active when you pick it again (mine read OpenRouter • Active), and the model row for LM Studio should name the identifier from step 1. I read the active provider back before and after the whole run and it was openrouter both times.
Step 4. Pin one Jira project to the local LLM
Stay in CogniRunner's admin page and go to Agents, then Setup, then Project configuration. Pick the project. Before the pin, my card read HRPIN · not configured yet with a chip saying Inherits the site.
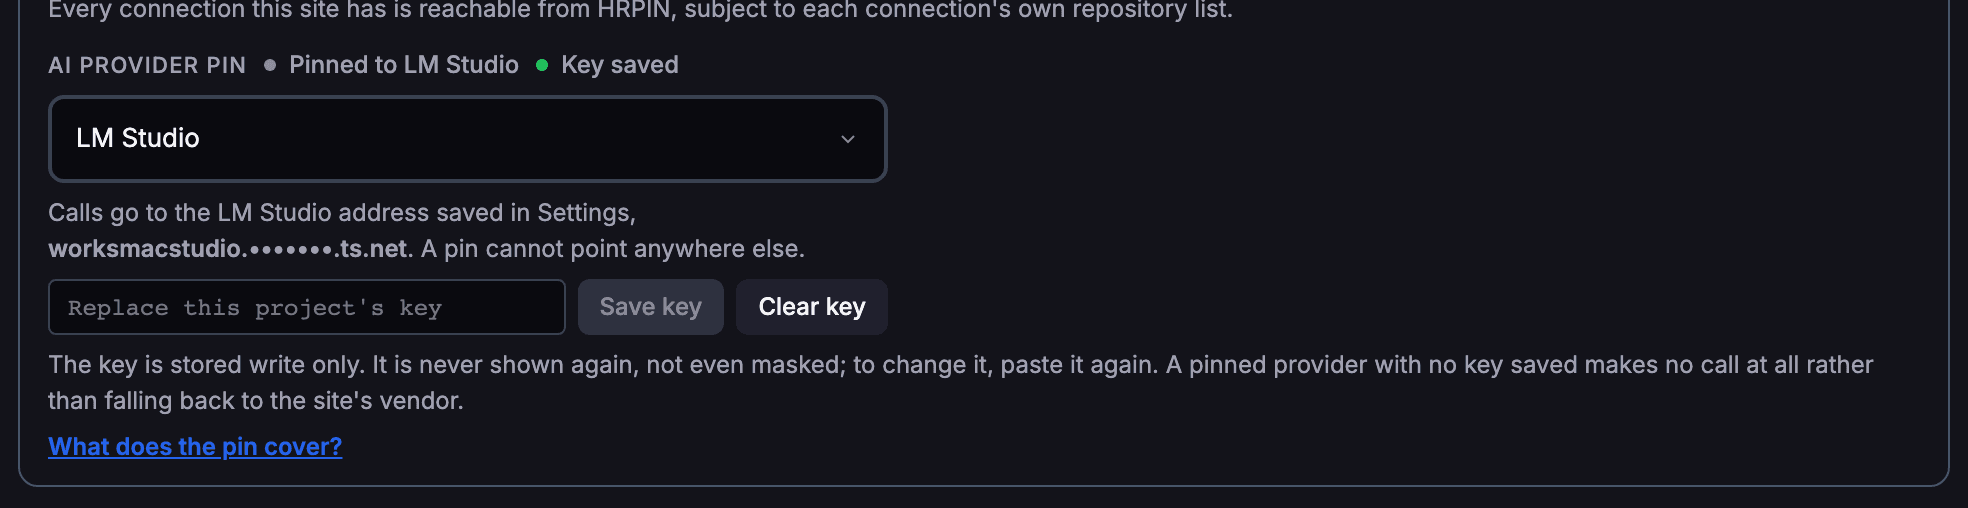
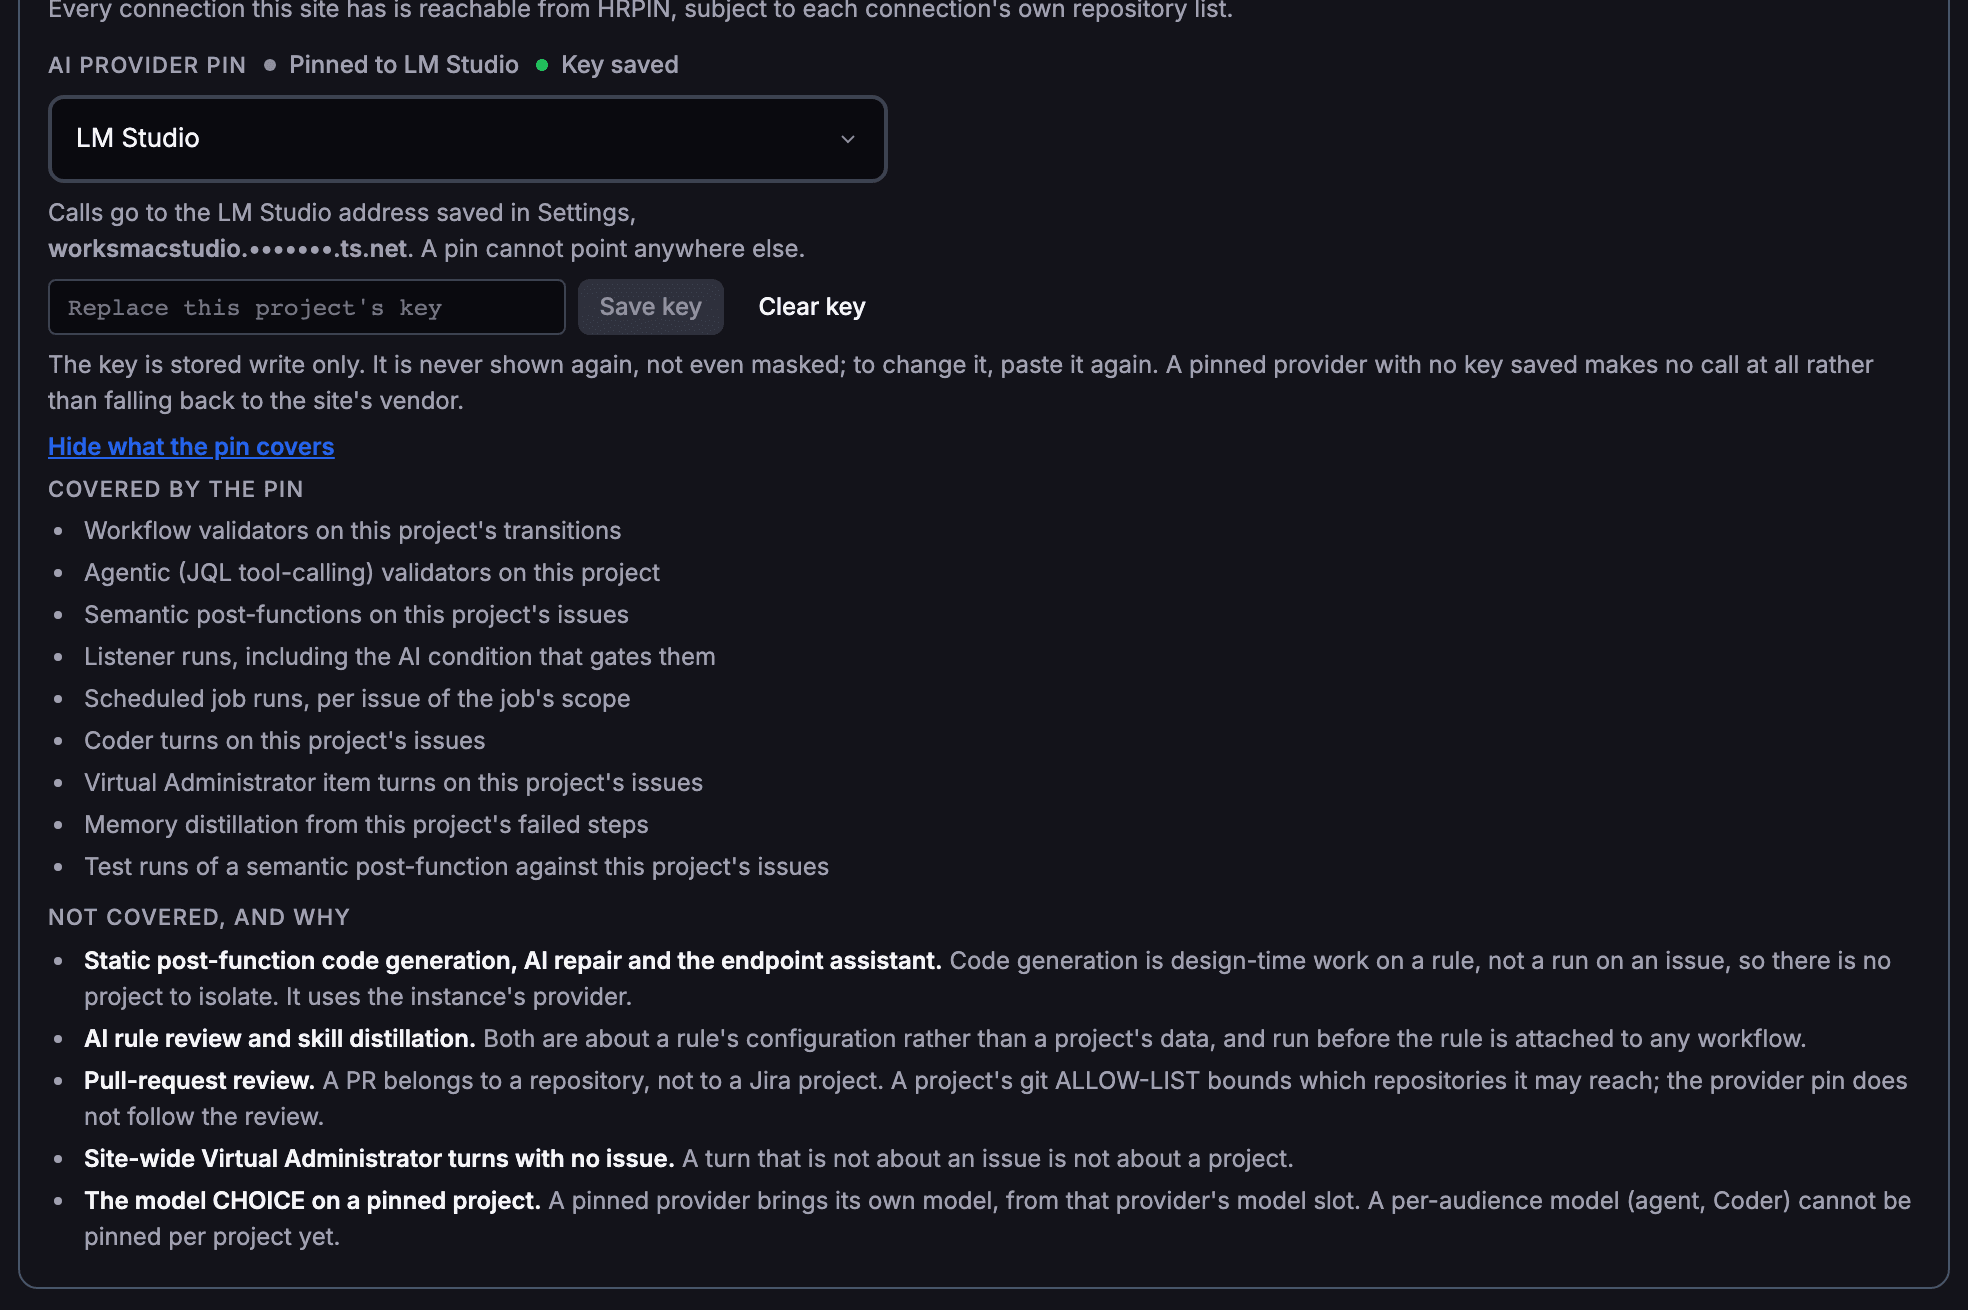
Scroll to AI PROVIDER PIN and choose LM Studio (it's the last of twelve options). The card tells you where the calls will go:
text
1Calls go to the LM Studio address saved in Settings, worksmacstudio.•••••••.ts.net. A pin cannot point anywhere else.
Click Save this project. Then paste the LM Studio API token from step 1 into the field under it and click Save key. (CogniRunner calls it a key. It's the same token.) Save key stays disabled until the project is saved, and the card says so.
The pin after Save this project and Save key, on a development build of 1.34.0 on our test site. The head reads Pinned to LM Studio and Key saved. The tailnet name is masked in the capture.
Check: the head of the section should read Pinned to LM Studio and Key saved, and a Clear key button should appear. Key saved means a token was stored. Nothing tests it at this point, and step 8 is about that.
Now click "What does the pin cover?" and read the list.
What the pin covers, as the card prints it on 1.34.0. Nine kinds of run on this project's issues go to the pinned provider. Five entries are not covered, and the card gives a reason for each.
It covers more than validators: semantic post-functions, listeners, scheduled jobs and agent turns on this project's issues go to the Mac too. Some work doesn't. If somebody asks CogniRunner to generate a rule's code for this project, the card says that call "uses the instance's provider", because it is "design-time work on a rule, not a run on an issue". Rule review and pull-request review are on the not-covered list as well.
Step 5. Add the Jira workflow validator on Send for Review
Atlassian's workflow docs describe what a validator does on Jira Cloud: "If a validator fails, the work item does not progress to the destination status of the transition". CogniRunner's is one of those with a prompt where you'd expect a script. I wrote about the idea in the validator post.
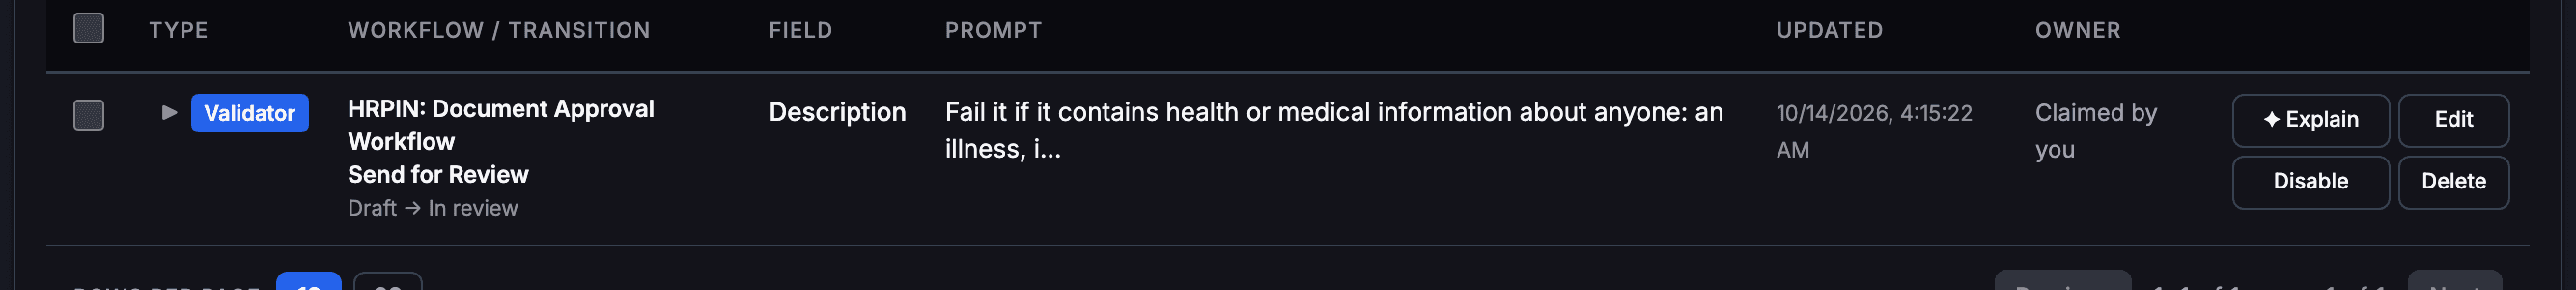
In Jira's workflow editor, add a validator to the Send for Review transition and choose the one named CogniRunner Field Validator. Its form asks for a Field to Validate (pick Description) and a Validation Prompt. This is the prompt from the video, unchanged:
text
1Fail it if it contains health or medical information about anyone: an illness, injury, surgery, sick leave, diagnosis or treatment. This is an HR request a manager sends to People Ops for approval. When it fails, say in one short sentence which detail must be removed. Otherwise it passes.
I should say how I added mine. The project was a throwaway, so I attached the validator through Jira's workflow REST API and registered it with CogniRunner's Rules API. I took the form's labels from our source, and I didn't open the editor today.
The validator in CogniRunner's Rules tab on our test site. Field reads Description, and the prompt column shows about the first 80 characters, so put the condition first.
Check: CogniRunner's Rules tab should show one row for your transition, with Description in the Field column and the start of your prompt.
Step 6. Send the request twice: Jira refuses, then lets it through
Here is the request. The people are invented.
text
1Change: raise base salary from 68,000 to 76,200 EUR.
2Effective date: 1 November 2026
3Approver: Elena Brandt (Head of Platform)
4Reason: Dana has covered two roles since the July reorg.
5Note: she is just back from three weeks of sick leave after back surgery, so let's get this through before her review.
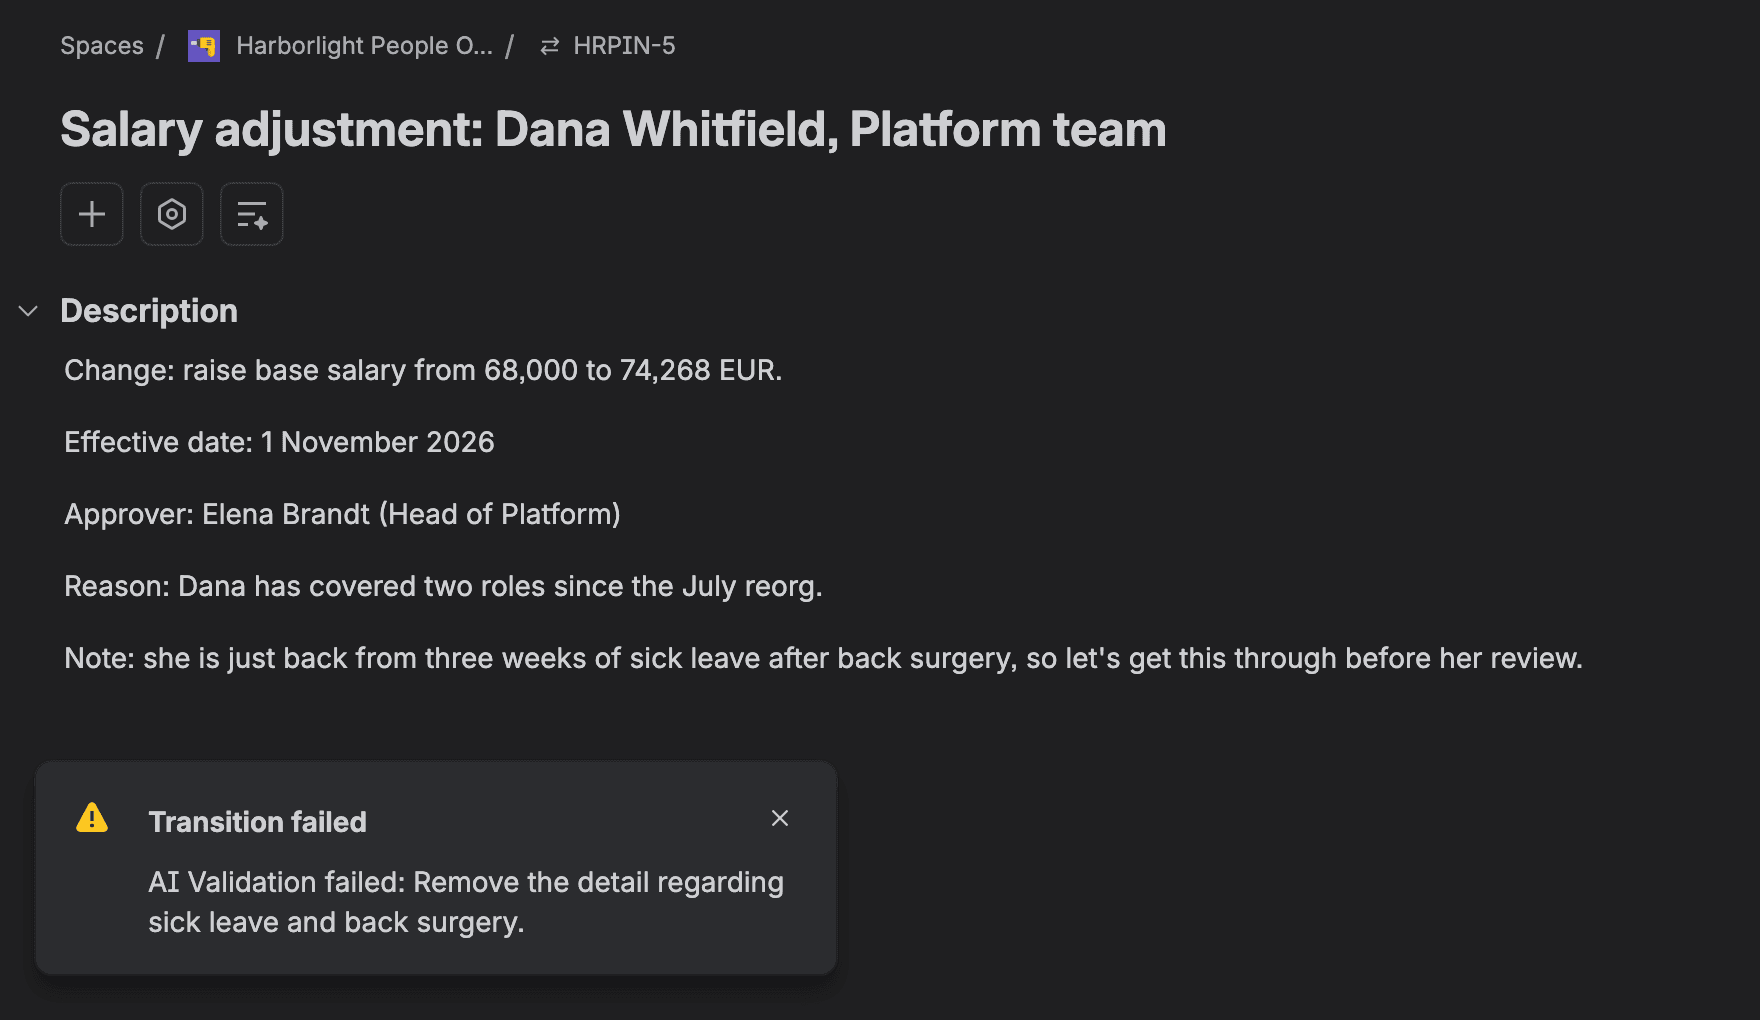
Click the status button and choose Send for Review. I did that in the browser for two of my eight rounds, and Jira's flag came up about three seconds after the click (3,329 ms and 2,822 ms).
Round 8 in the Jira issue view on our test site. The flag reads Transition failed, and under it is the model's own sentence: Remove the detail regarding sick leave and back surgery. I cut the empty middle of the page out of this capture.
My other six rounds went over Jira's REST API, which is also how a script or an integration would meet this validator. These are the result lines my script logged for the first round, without its timestamps:
text
1WITH the health sentence: POST /rest/api/3/issue/HRPIN-5/transitions {"transition":{"id":"21"}} -> HTTP 400 in 6413 ms
2   body: {"errorMessages":["AI Validation failed: Remove the mention of sick leave and back surgery in the note section."],"errors":{}}
3   status now: Draft
4sentence REMOVED: same POST -> HTTP 204 in 2938 ms
5   body: (empty)
6   status now: In review
So a refusal is HTTP 400 with the model's sentence in errorMessages, and a pass is an empty 204. That first refusal took 6.4 seconds. The model's share was 0.8, and I don't know where the rest went. The later refusals took 2.3 to 3.4 seconds and the passes 2.5 to 2.9.
Check: with the sentence in, the request should stay in Draft and you should see a message that starts with AI Validation failed:. Take the Note line out and send again, and the status should change.
All 8 rounds gave the same verdict, but the model never gave the same reason twice. I got 8 different sentences. They ran from "Remove the detail mentioning sick leave and back surgery." to "The text mentions specific medical details including 'sick leave' and 'back surgery' which must be removed."
Illustration, generated locally with FLUX. The validator read one field and refused the request 8 times out of 8 while the sentence about surgery was in it. The briefcase was never checked.
Step 7. Read the LM Studio log: two requests, no cloud fallback
How do you know the Mac answered? CogniRunner's Execution Logs tab shows the verdict and the reason, but it doesn't print which model answered. I'd take the proof from LM Studio's own log.
LM Studio streams it with one command. The flags below print each prompt and each answer as JSON, with the speed.
bash
1lms log stream --source model --filter input,output --json--stats
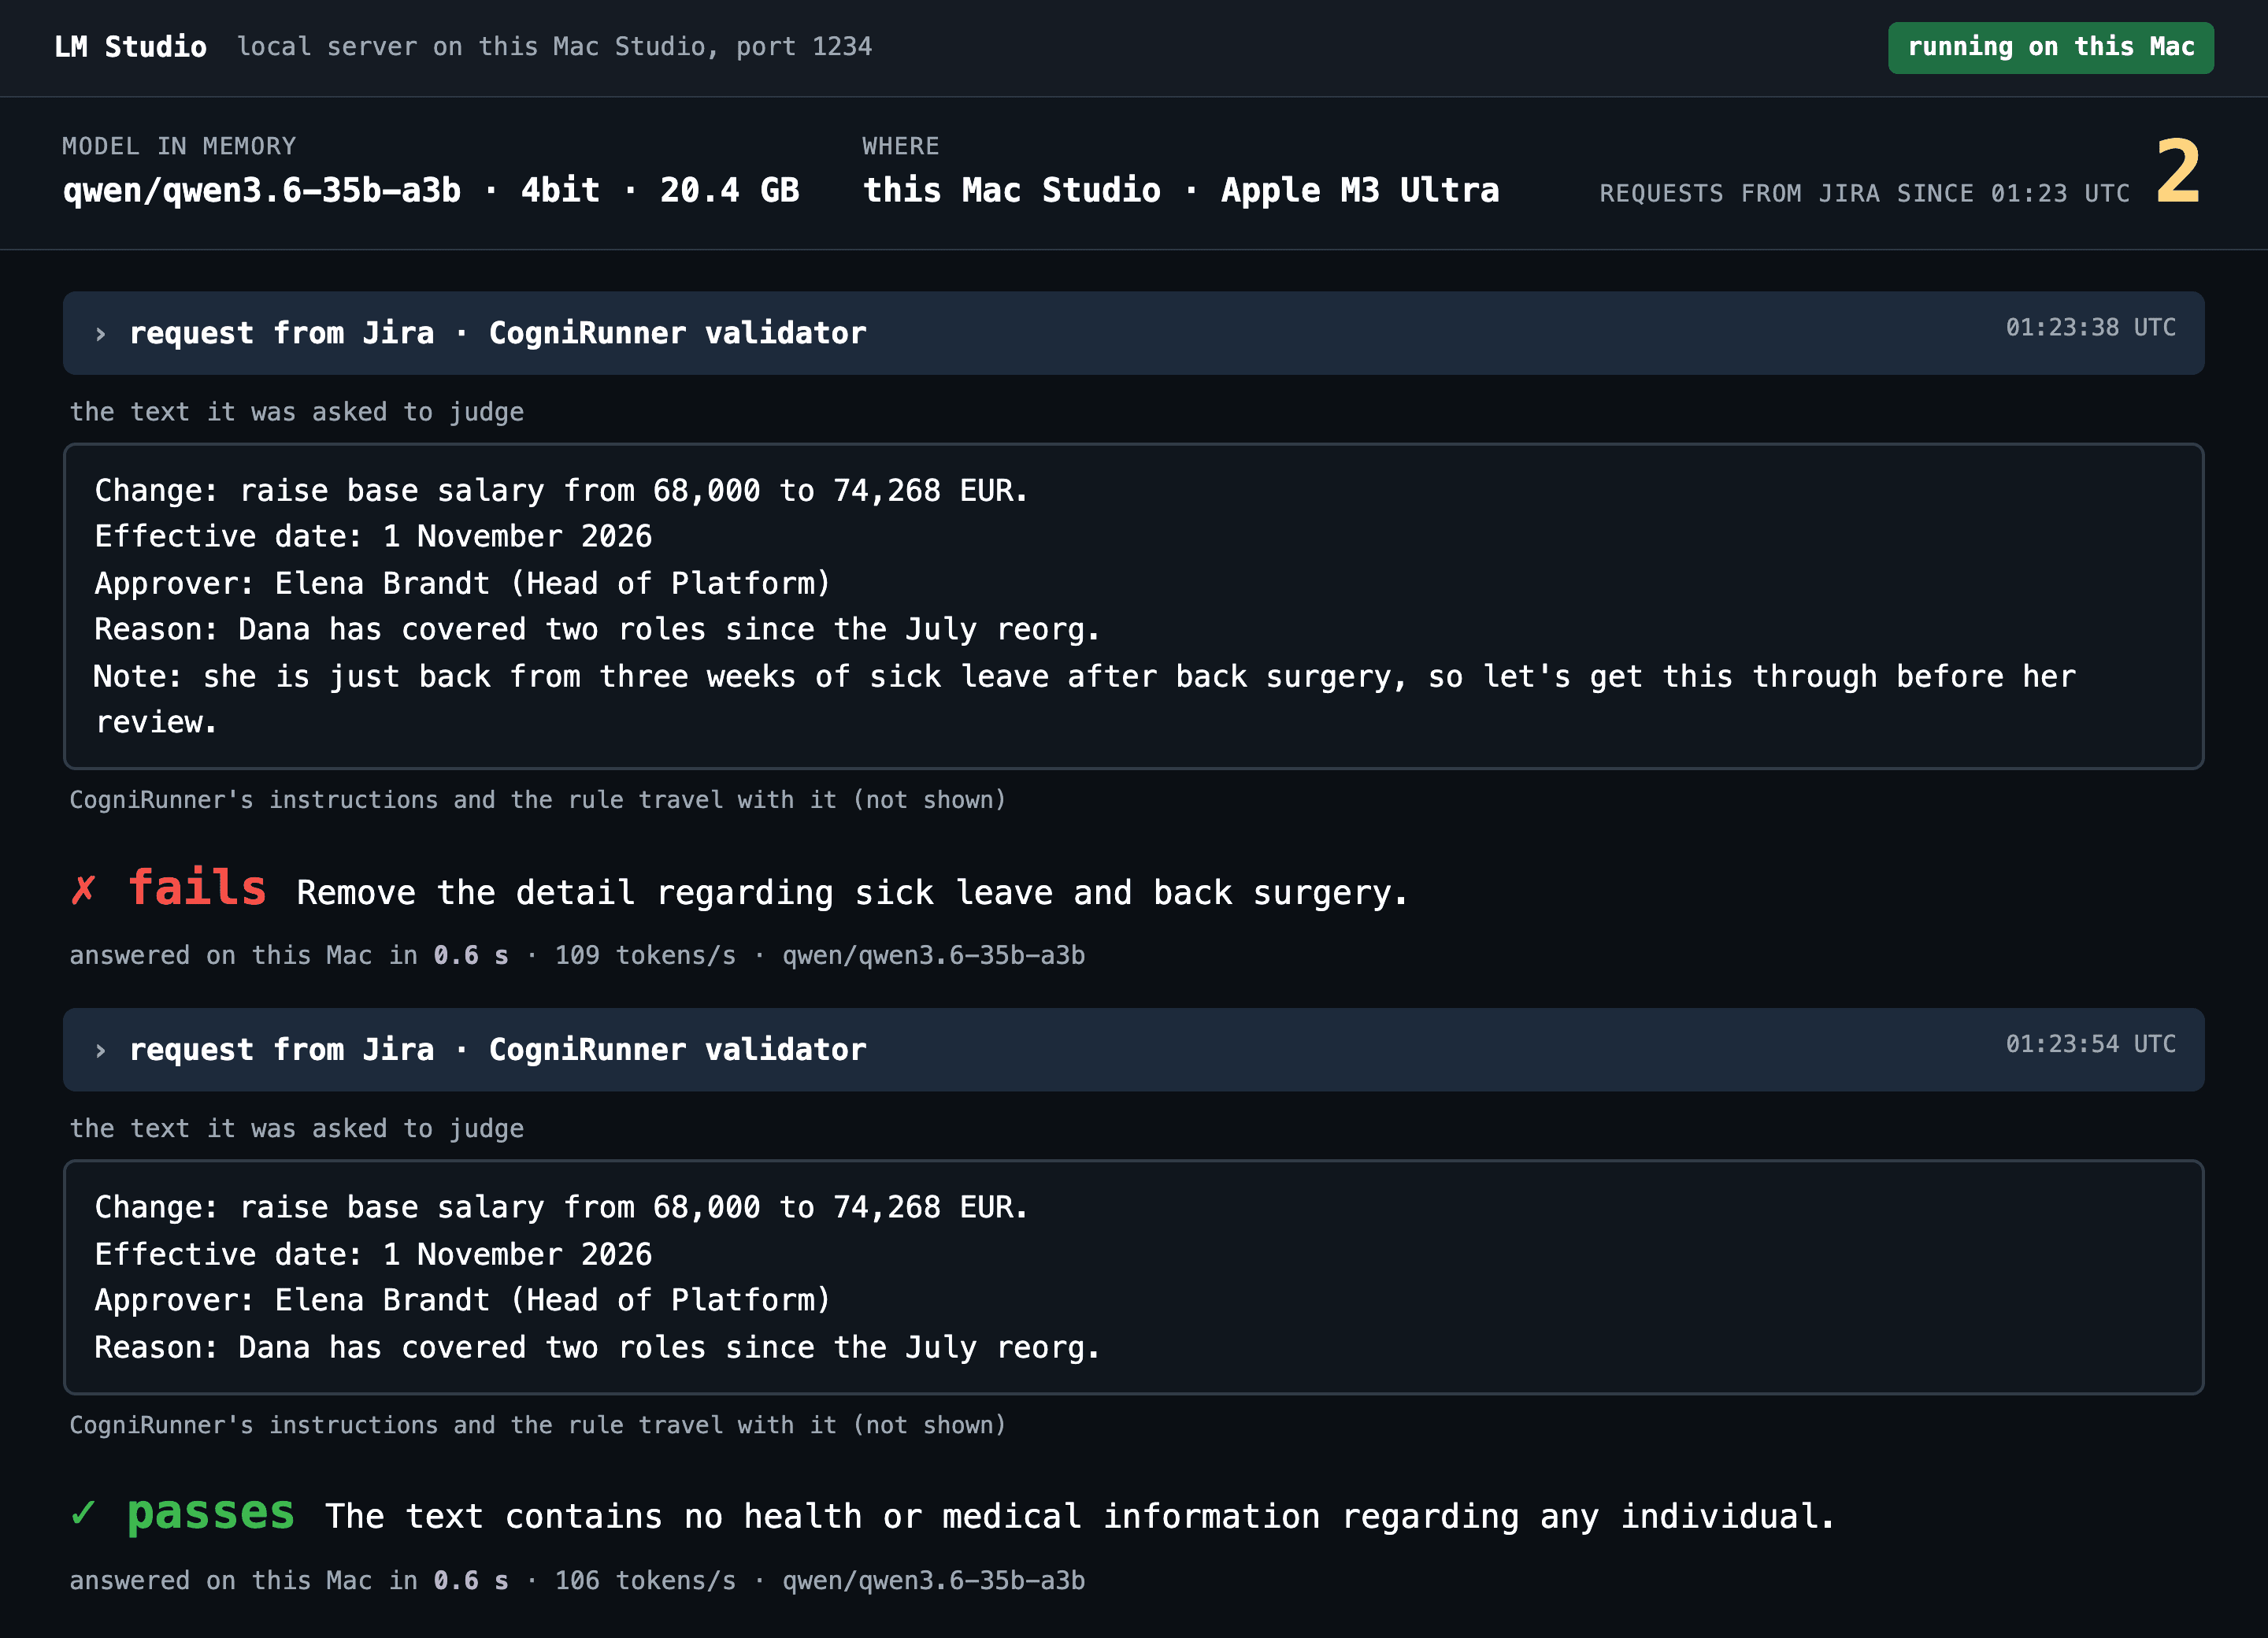
I didn't keep a raw terminal capture of that stream. We have a small viewer page that runs this exact command and renders what it prints, and this is what it held after round 8:
LM Studio's log stream for round 8, rendered by our own viewer page. Two requests from Jira, at 01:23:38 and 01:23:54 UTC. The first fails with the sentence Jira showed in the flag. It was answered on the Mac in 0.6 seconds at 109 tokens a second.
This is how my script printed the viewer's events for the first round. I shortened the two request texts where you see / ... / and left the date off the timestamps:
text
101:16:01.642Z REQUEST  qwen/qwen3.6-35b-a3b | CogniRunner validator | Change: raise base salary from 68,000 to 76,200 EUR. / ... / Note: she is just back from three weeks of sick leave after back surgery, so let's get this through before her review.
201:16:02.434Z ANSWER   qwen/qwen3.6-35b-a3b | 0.8 s | 108 tok/s | prompt 515 tok | out 25 tok | {"isValid": false, "reason": "Remove the mention of sick leave and back surgery in the note section."}
301:16:05.326Z REQUEST  qwen/qwen3.6-35b-a3b | CogniRunner validator | Change: raise base salary from 68,000 to 76,200 EUR. / ... / Reason: Dana has covered two roles since the July reorg.
401:16:06.078Z ANSWER   qwen/qwen3.6-35b-a3b | 0.8 s | 105 tok/s | prompt 488 tok | out 26 tok | {"isValid": true, "reason": "The text contains salary adjustment details and does not contain health or medical information."}
Check: after one refusal and one pass you should see two new requests in the stream, and the reason in the first answer should be word for word the sentence Jira showed.
Across the 16 answers the model took 0.6 to 0.8 seconds and wrote 20 to 37 tokens, at 100 to 110 tokens a second. The prompt was 515 tokens for a Description of about 50 words, because CogniRunner's own instructions and your prompt travel with the field. All of that is in LM Studio's input log if you want to read what your model was really asked.
Then I checked that a project without a pin still goes to OpenRouter. I put the same validator on a second project and sent it the same text. These are two lines from that run's log:
text
1WITH the health sentence: POST /rest/api/3/issue/COGTEST-3057/transitions {"transition":{"id":"9741"}} -> HTTP 400 in 4175 ms
2   body: {"errorMessages":["AI Validation failed: Remove the detail that Dana returned from sick leave after back surgery."],"errors":{}}
LM Studio's log for that run had 0 requests and 0 answers. CogniRunner's log rows, read over its REST API, say modelUsed=openai/gpt-6-luna for that pair and modelUsed=qwen/qwen3.6-35b-a3b for the pinned project. Run this control on your own site too.
Step 8. Save a wrong token once and find the FAIL-OPEN row
I pasted a wrong token into the project card and clicked Save key. The card still read Key saved. Then I sent the request with the surgery sentence in it:
text
1WITH the health sentence: POST /rest/api/3/issue/HRPIN-5/transitions {"transition":{"id":"21"}} -> HTTP 204 in 2323 ms
2   body: (empty)
3   status now: In review
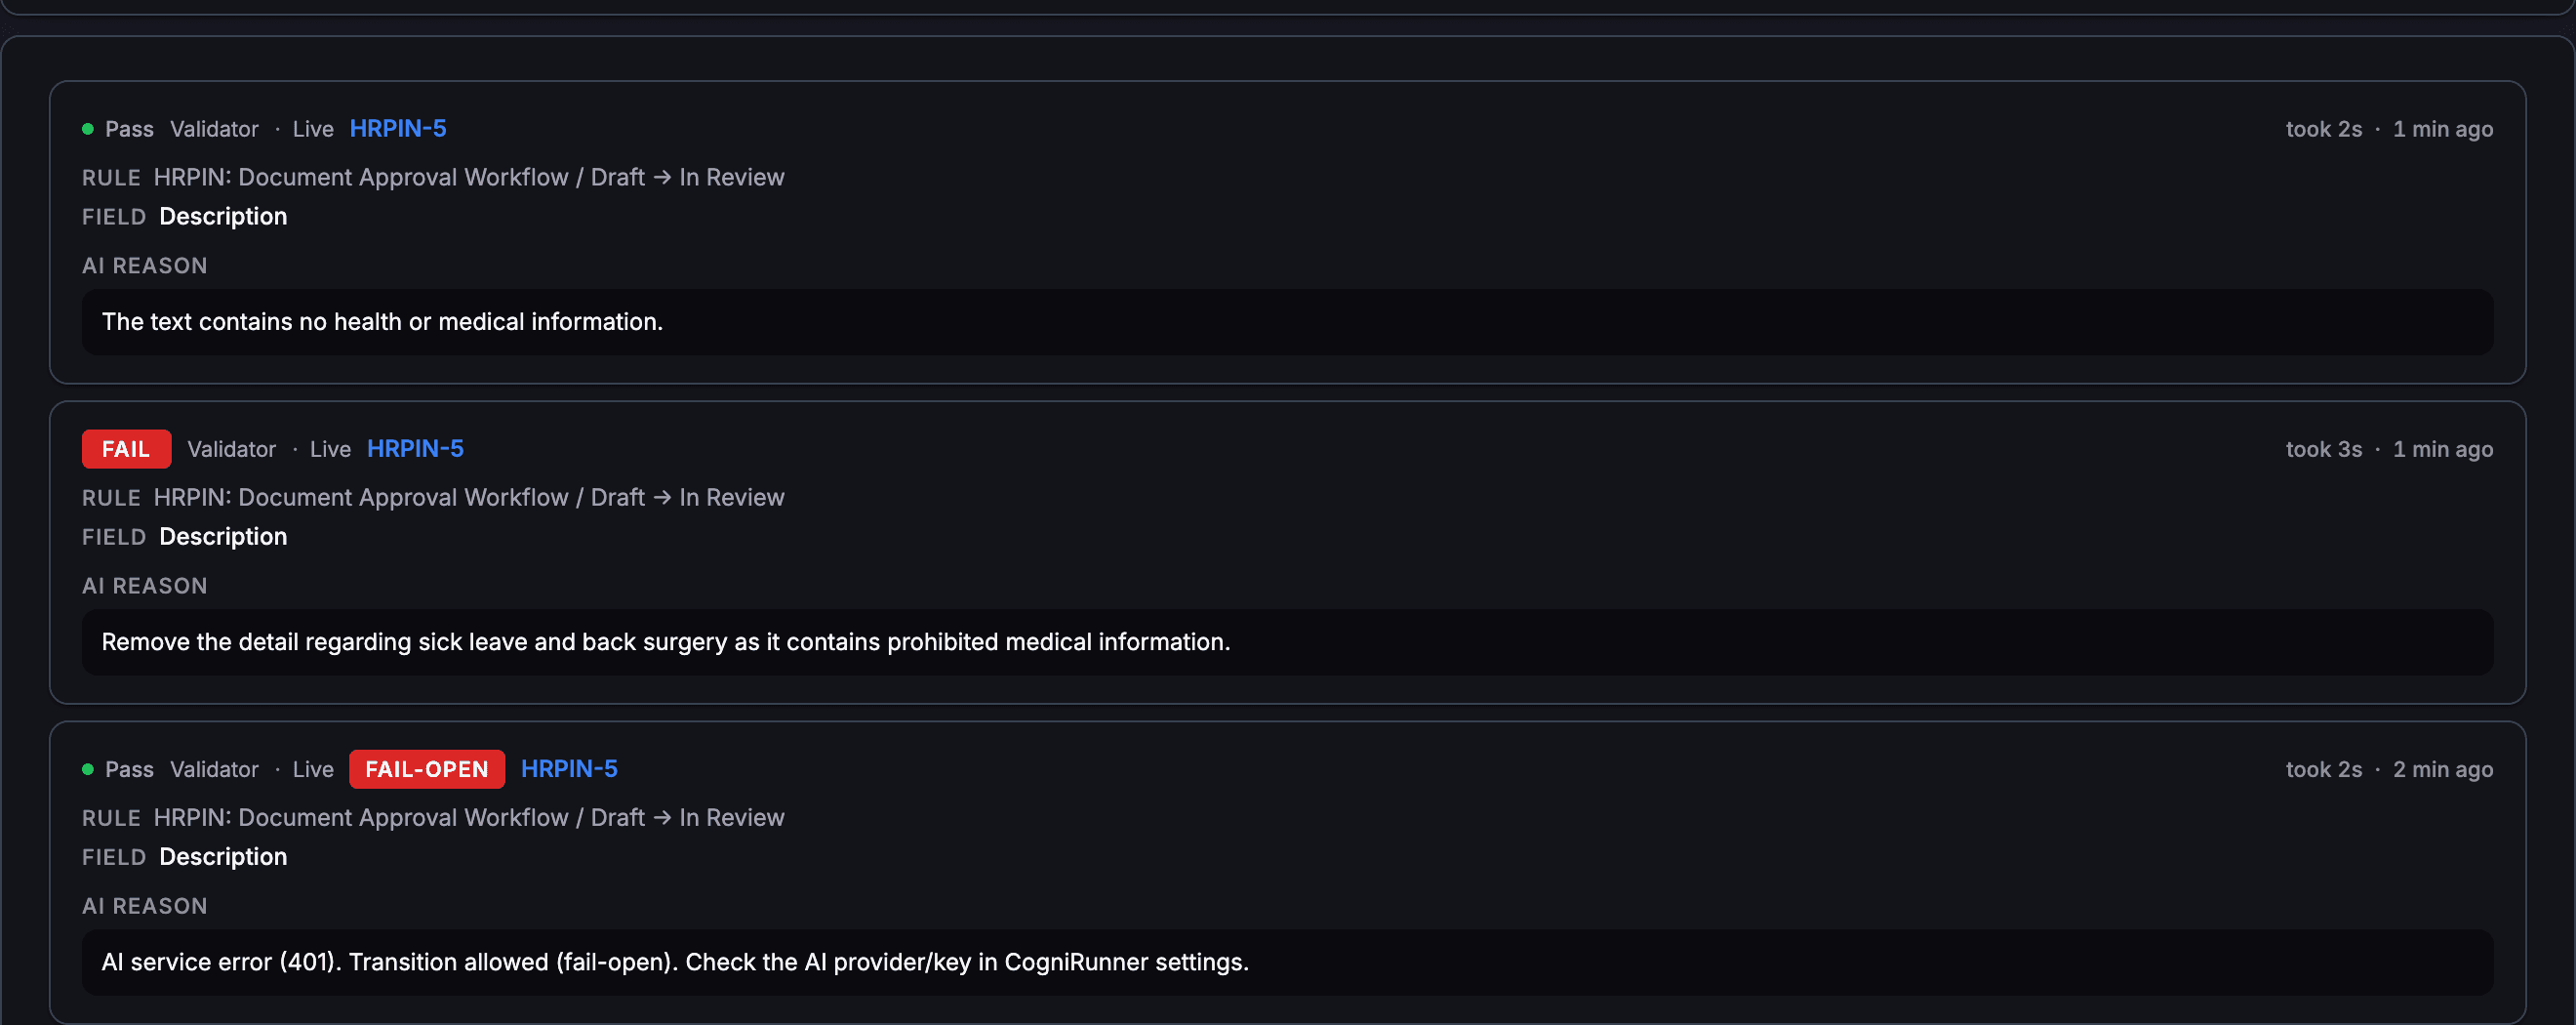
It went through, health sentence and all. LM Studio turned the call away with a 401 before the model saw anything (its model log had 0 requests), and CogniRunner's validator let the move happen. You find out in Execution Logs:
Execution Logs on our test site. The bottom row is from my run with no token on the LM Studio pin: a Pass with a red FAIL-OPEN chip and the reason AI service error (401). Transition allowed (fail-open). The wrong-token run wrote the same reason. Above it is an ordinary refusal.
text
1AI service error (401). Transition allowed (fail-open). Check the AI provider/key in CogniRunner settings.
Check: you should see a Pass row with a red FAIL-OPEN chip and that reason. Then paste the right token again, send a request with a new salary figure, and confirm the refusal is back. Mine was.
I tried two more broken pins. With the project pinned to Anthropic and no key saved, CogniRunner made no call at all and wrote this:
text
1AI validation was not run. Transition allowed (fail-open). Project HRPIN pins its own AI provider but no key has been saved for it, so nothing was sent. An app administrator sets the key in the project's configuration. Nothing was sent to the instance's default provider, deliberately.
With the project pinned to LM Studio and no token, I expected the same sentence, because the card says "A pinned provider with no key saved makes no call at all". I got the 401 row again. CogniRunner lets LM Studio run without a token (off is LM Studio's default), so it called the saved address with none and my server refused it. So the card's sentence is too broad for LM Studio. We should fix the wording.
So of my three broken pins, one made no call and two called my Mac and got a 401. None of the three log rows names the site's model, and I didn't open OpenRouter's usage log to confirm it from that side. All three requests went through unread.
Is failing open the right default? For a check like this, I think so. A Mac that's asleep shouldn't freeze HR's queue. But I didn't see an alert anywhere, only the row, so somebody has to look at Execution Logs now and then.
If it didn't work
Jira refuses, but LM Studio's log is empty. You probably sent text the app has already judged. CogniRunner keeps a verdict for 10 minutes, and the field's text is part of the key. I sent the identical request twice, seconds apart. The second refusal came back in 1,367 ms with 0 requests in the log, and the app's row ended with (cached verdict). Change the text (I changed the salary figure each round) or wait.
The request goes through when it shouldn't. Open Execution Logs and look for the red FAIL-OPEN chip. AI service error (401) means the project's token is wrong or missing. Paste it again on the project card.
The first try after a quiet hour is slow. A validator has 20 seconds. My first direct call of the session took 2.8 seconds to warm the model, and our video session measured 12 seconds on an idle model's first answer, which is uncomfortably close. Past 20 seconds the default is to allow the move and log why. 1.34.0 added a switch for this case, off by default, under Slow self-hosted providers in Settings. The release note says that with it on, "the transition is refused with a message saying the check is still running, while the check finishes in the background." I haven't tested the switch, a sleeping Mac or an unloaded model, because my model answered in under a second every time and other work was using it.
The Rules tab says No rules match. That happened to me because I attached the validator over REST. It appeared after I ran discover and register on CogniRunner's Rules API.
What this setup doesn't do
A validator reads one field. Mine read the Description, and I didn't test the same sentence in a comment or the Summary. I wouldn't call this a security control or sell it to an auditor as one. I'd use it to catch the manager who types a diagnosis into a salary request, before the approvers read it.
CogniRunner doesn't carry the Runs on Atlassian badge with any provider. Atlassian's page for the badge says "Your app must not egress data, with the exception of egress for analytics purposes", and an app that calls a model you host has to egress.
My run was on a development build on our test site, with invented requests, and I ran nothing on production today. I tested one prompt on one kind of sentence, which says little about how the model handles a vaguer request. If Rovo is the AI you're comparing this with, Rovo agent permissions vs CogniRunner approvals covers the other side, and the product page has the rest of CogniRunner.
What you have now
Key takeaways
One Jira Cloud project whose validators and other issue-level AI runs are answered by a model in LM Studio on your Mac.
A site that still uses its cloud provider for the other projects, and for generating a rule's code.
An https address for LM Studio that answers 401 to a caller with no token.
LM Studio's log as the proof of which machine answered, with an unpinned project as the control.
A FAIL-OPEN row you made yourself in step 8, so you recognise the next one.
To go back, choose "Use the site's provider" in the same list on the project card and save. I removed my pin through the app's API during cleanup and then deleted the project, so I haven't watched that click. The post where LM Studio support arrived in CogniRunner has the background.



Comments
0Add a comment